Introduction
Frustrated customers close browser tabs rapidly whenever mobile applications freeze during payments. Modern digital services require continuous uptime to protect business revenue. Site Reliability Engineering keeps large software platforms operating smoothly without disruptive crashes. Technologists often call this discipline SRE. This modern approach blends software coding skills with traditional systems management. Such a balance produces resilient, secure, and fast web portals. Thousands of professionals visit SRESchool.com to master these core practices. The educational resource shows learners practical methods to prevent service disruptions before clients encounter them.
What Is SRESchool.com?
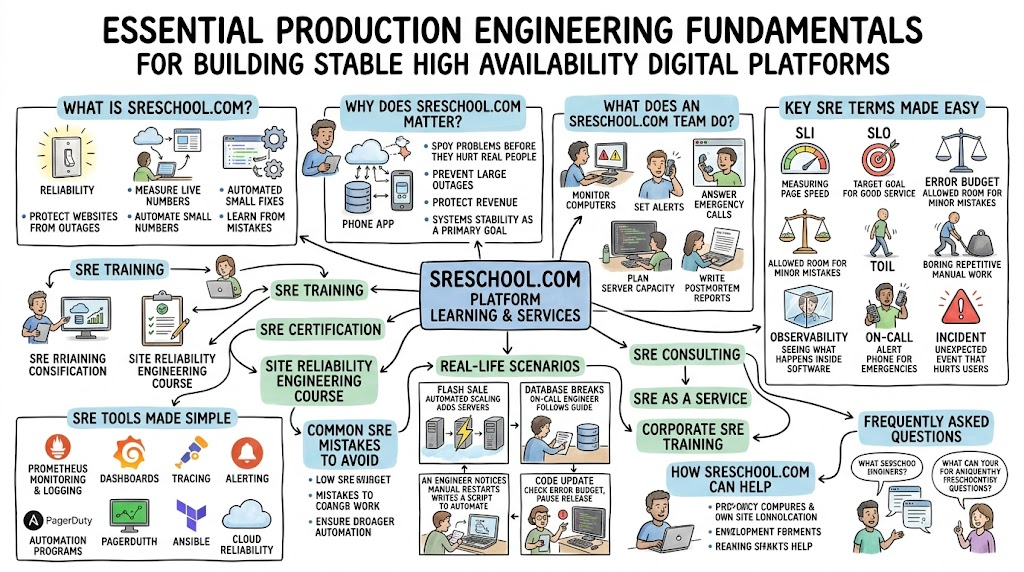
Reliability practices approach computer operations as a programming challenge rather than a manual chore. Consider a home refrigerator that preserves food safely throughout the entire year. Reliable engineering guarantees that web applications return accurate data whenever users click buttons. SRE empowers modern teams to maintain dependable services across diverse cloud networks. Technicians follow system metrics continuously using automated telemetry software. They build instant alert channels that flag subtle code flaws early. Teams eliminate tedious human routines by writing intelligent automation scripts. Afterward, engineers review every technical failure together to improve their collective work.
Why Does SRESchool.com Matter?
Contemporary businesses run upon distributed cloud servers, large databases, and complex network paths. An unnoticed software defect can bring down an entire enterprise payment pipeline. Countless retail customers lose the ability to complete essential transactions immediately. SRE prevents these severe breakdowns through continuous monitoring and strict release testing. Specialists resolve emerging warnings long before small glitches cascade into widespread platform outages. Companies protect their financial health when production clusters remain active. Forward-thinking organizations establish service reliability as an essential priority from the opening day.
What Does an SRESchool.com Team Do?
Engineers inside an SRE unit defend production clusters through several vital daily duties. They study live operational dashboards to evaluate network latency, memory usage, and processor load. Automated watchdogs ping selected engineers whenever an application exceeds safe performance limits. The designated engineer isolates the underlying bug and restores normal operations quickly. Staff members write clean utility scripts that replace repetitive computer administration tasks. They analyze future usage trends so unexpected visitor spikes never crash server nodes. Furthermore, specialists inspect code architectures to eliminate brittle dependencies across services. Then, they publish transparent postmortems to educate their organization on safer methods.
Key SRE Terms Made Easy
Reliability specialists employ distinct industry terms to describe platform stability clearly. A Service Level Indicator, or SLI, measures real system behavior such as request latency. A Service Level Objective, or SLO, states the target performance your group promises to deliver. An Error Budget calculates the exact duration of system instability your team permits. Toil represents repetitive operational chores that a software script can execute automatically. Observability lets engineers understand internal software states by analyzing external telemetry data. On-call shifts designate available engineers to remediate sudden overnight server crashes. An incident marks any unanticipated disruption to normal production service.
| SRE Term | Simple Meaning | Example |
| SLI | An actual measurement of live performance | The shopping cart updates within 150 milliseconds |
| SLO | The uptime target the organization promises | Sustain 99.9 percent service availability each quarter |
| Error Budget | The permitted allowance for small outages | The team can spend 43 minutes of downtime |
| Toil | Boring manual effort repeated frequently | Entering manual commands to flush database caches |
| Observability | Deep insight into hidden software behavior | Examining distributed traces to pinpoint database latency |
| Incident | An unexpected drop in system availability | A faulty update stops customer order confirmations |
What Is SRE Training?
Aspiring engineers start their professional transition by taking part in structured SRE Training. Students study core operational concepts like service level objectives and risk budgets. Course modules demonstrate how to gather system metrics and eradicate manual toil. Mentors guide students through emergency drills to cultivate calm decision-making during outages. Students build test environments to practice capacity planning and cloud auto-scaling firsthand. Practical lab exercises impart valuable engineering capabilities far better than reading textbooks. Practicing system restorations on SRESchool.com gives engineers authentic operational confidence.
What Is SRE Certification?
An industry SRE Certification assesses your practical competence in running production systems. A Certified Site Reliability Engineer demonstrates proven talent in system monitoring, alerting, and rapid remediation. Structured assessments verify that you understand distributed setups, rollback techniques, and automated recovery. Still, official credentials cannot replace genuine hours spent supporting production environments. You must assemble practical projects and troubleshoot realistic failure scenarios yourself. Technology employers prize valid credentials alongside demonstrated operational problem-solving skills.
What Is a Site Reliability Engineering Course?
A well-designed Site Reliability Engineering Course walks you through every major operational milestone. Students begin by grasping foundational principles before collecting simple health indicators from test nodes. Next, learners design interactive dashboards to view performance metrics in real time. Following that, they apply error budgets to balance rapid feature releases against platform stability. Instructors trigger simulated cloud emergencies so learners test response procedures under realistic conditions. Students then program reliable automation tools to eliminate manual administrative chores. Finally, candidates operate fault-tolerant infrastructure inside public cloud environments.
SRE Tools Made Simple
Engineers utilize specialized software instruments to supervise complex distributed infrastructure. Metric collectors like Prometheus gather numerical indicators from running host machines. Visualization engines like Grafana transform those raw measurements into readable charts. Centralized logging engines store system records so engineers can search for root causes easily. Tracing platforms like OpenTelemetry follow individual user requests across interconnected application services. Alerting daemons notify on-call specialists when server resources near exhaustion. Meanwhile, cloud configuration frameworks execute software updates across server fleets without human interaction.
| Learning Area | What Learners Can Practice |
| Metric Aggregation | Scrape machine statistics using Prometheus |
| Visual Telemetry | Assemble interactive health monitors with Grafana |
| Request Tracking | Trace transaction pathways via OpenTelemetry |
| Emergency Drills | Roll back problematic software releases safely |
| Workflow Automation | Script automated maintenance using Python |
| Cloud Resiliency | Establish dynamic scaling policies on cloud clusters |
Real-Life Scenarios / Experiences
Engineers encounter diverse technical surprises while supporting production infrastructure on a daily basis.
- A streaming media platform experiences massive viewership during a championship athletic broadcast. The operations team notices high memory pressure on Grafana and provisions supplementary computing instances immediately.
- A developer deploys a broken database query that locks the customer checkout service. Automated alarms notify the on-call engineer, who cancels the deployment within two minutes.
- A support technician manually clears temporary system directories every Friday evening. The team creates an automated scheduled job that cleans obsolete storage without human intervention.
- A severe regional power failure takes an entire cloud data facility offline instantly. Redundant routing policies direct all customer traffic to an operational data center seamlessly.
What Is SRE Consulting?
Securing SRE Consulting delivers veteran industry guidance straight to your engineering department. Experienced advisers inspect your existing cloud topology to identify risky operational bottlenecks. They assist engineering leaders in establishing realistic SLO targets for critical services. Furthermore, consultants reconfigure noisy alert channels so teams only respond to actionable issues. They introduce sustainable workflows that help developers reduce exhausting operational toil. Above all, specialists furnish an actionable adoption strategy tailored to your company goals. Your technology organization adopts durable engineering habits that protect system stability permanently.
What Is SRE as a Service?
Growing companies frequently adopt SRE as a Service to secure continuous platform oversight. External specialists monitor your cloud deployments around the clock without requiring full-time internal hires. These experts intervene immediately when application anomalies emerge outside regular office hours. They conduct regular architectural reviews to discover configuration flaws and performance regressions. Moreover, they configure automated cloud provisioning so your services expand seamlessly as demand rises. Organizations must establish clear operational boundaries before engaging external engineering teams. Explicit expectations ensure that both partners strive toward identical uptime objectives.
What Is Corporate SRE Training?
Comprehensive Corporate SRE Training unites entire technical units behind standardized operational standards. Expert educators customize curriculum content around the specific technology stack your business operates. Software programmers and infrastructure administrators practice resolving simulated outages collaboratively within isolated labs. They learn identical mathematical models to calculate user satisfaction accurately. Teams also write custom software automation to eliminate their most frustrating manual duties. Shared laboratory exercises transform workplace blame into rapid, unified cooperation during live production emergencies.
Common Mistakes to Avoid When Choosing Reliability Methods
Technology organizations often commit costly mistakes when deploying reliability frameworks for the first time.
- Teams pursue impossible perfection by declaring a one-hundred-percent availability target for services.
- Engineers configure hundreds of non-critical alerts that exhaust responders during sleeping hours.
- Leadership ignores mounting operational toil until valuable engineers resign from exhaustion.
- Developers push significant software features without stress-testing their resilience under peak traffic.
- Staff conceal technical errors instead of publishing honest, blameless post-incident reviews together.
- Companies purchase costly monitoring software without training their engineers to use the toolsets.
- Technicians neglect regular disaster recovery simulations until a major cloud failure occurs.
- Executives consider reliability work a brief, temporary project instead of an ongoing discipline.
How SRESchool.com Can Help
SRESchool.com offers an integrated training and advisory platform for modern systems engineering. Beginning engineers can take a comprehensive SRE Course to gain foundational technical skills. Practicing engineers can prepare for an SRE Certification to showcase verified cloud capabilities to prospective employers. The learning center provides an extensive SRE Tutorial catalog detailing widely adopted SRE Tools. Organizations can schedule Corporate SRE Training to align development and systems teams on proven practices. Furthermore, companies utilize SRE Consulting to eliminate painful manual workflows. Enterprises can also implement SRE as a Service for continuous, proactive infrastructure management.
Frequently Asked Questions
1. What does Site Reliability Engineering mean in plain words?
Site Reliability Engineering treats computer operations as a software development challenge. Engineers build automated tools to handle server maintenance, system backups, and software releases without manual effort. They place telemetry software across networks to track system wellness day and night. When servers fail, engineers remediate the defect immediately. Afterward, the team studies the root failure to prevent similar problems in the future.
2. Can a complete beginner learn SRE?
Aspiring engineers can master SRE by pursuing an organized, practical learning curriculum. You should master fundamental Linux commands, networking concepts, and entry-level programming first. Next, explore fundamental reliability topics like system metrics, availability targets, and risk margins. Isolated cloud sandboxes enable you to practice real-world troubleshooting safely. Structured training gives beginners a clear roadmap toward rewarding engineering roles.
3. What is an SLO?
An SLO stands for Service Level Objective. It represents an agreed target for application performance and uptime. A team might specify that its web API must process requests within 300 milliseconds. This shared objective ensures that programmers and operations personnel work toward identical standards. It preserves customer satisfaction without requiring impossible system perfection from engineers.
4. What does an Error Budget do?
An Error Budget defines the exact amount of downtime a digital service can safely endure. Complex software platforms inevitably encounter small interruptions or network delays occasionally. If your application targets ninety-nine percent uptime, your error budget allows one percent downtime. Developers spend this margin to deliver new product features rapidly. When the budget expires, engineers pause releases to eliminate bugs.
5. What is the meaning of toil in SRE?
Toil refers to repetitive, manual computing chores that produce no lasting value for a business. Typing terminal commands to restart a frozen application every morning represents classic toil. This manual work expands steadily as user numbers climb. Reliability teams write automated software to handle these boring tasks completely. Eradicating toil provides engineers with valuable time to design exciting product features.
6. What is the main difference between DevOps and SRE?
DevOps provides a cultural philosophy that promotes close collaboration between software creators and systems administrators. SRE supplies the exact operational framework that translates that collaborative mindset into daily practice. If you view DevOps as a general commitment to personal health, SRE represents your specific daily exercise plan. Both methodologies help technology enterprises release resilient applications rapidly.
7. Why do systems need observability?
Observability enables engineers to inspect the inner performance of distributed applications during production execution. Traditional monitoring tools only announce whether a server is running or offline. Observability instruments uncover sluggish database operations and failing network calls early. Engineers inspect logs, traces, and metrics to fix complicated software issues quickly. Deep observability prevents minor glitches from triggering massive service outages.
8. What does being on-call mean?
Holding an on-call pager means an engineer stays ready to address critical production emergencies. When an online service stalls during the night, an automated system pages that responder. The technician opens their computer, investigates the breakdown, and restores service quickly. Teams rotate this pager duty among staff so no single person suffers fatigue. Thoughtful schedules protect team members from workplace exhaustion.
9. What happens during a postmortem meeting?
Engineers participate in a postmortem review shortly after resolving a critical platform failure. The entire engineering group gathers to discover why the outage took place. Leaders explicitly forbid individual blame and focus strictly on broken software safeguards. Attendees pinpoint confusing alerts or missing tests that allowed the bug to reach production. Afterward, they implement automated fixes to eliminate that failure mode permanently.
10. Which programming languages do SREs use?
Reliability engineers primarily write their automation programs using Python or Go. Python provides an accessible syntax that makes scripting administrative jobs fast and simple. Go executes with exceptional efficiency and powers industry-standard cloud technologies like Docker. Many practitioners also construct shell scripts for quick system tasks inside Linux environments. Learning any of these languages builds a solid technical base.
11. What is the role of an SRE consultant?
An SRE consultant serves as an external specialist who helps organizations stabilize fragile software environments. These advisers review existing infrastructure setups and uncover dangerous architectural bottlenecks. Consultants also instruct in-house engineering groups on executing clear incident response procedures. They advise executives on establishing achievable, business-aligned availability targets. Their recommendations assist companies in lowering cloud bills and avoiding downtime.
12. How does SRE save money for businesses?
Reliability engineering saves organizations substantial money by preventing extended application outages. When an online store stalls, dissatisfied consumers take their payment details to competitor platforms. SRE also cuts unnecessary hosting costs through rigorous infrastructure capacity planning. Automation relieves engineers from manual duties so they can build revenue-generating products faster. Dependable digital platforms preserve brand trust and support steady commercial growth.
CONCLUSION
Contemporary businesses rely upon Site Reliability Engineering to maintain steady application performance for global audiences. Uniting software development concepts with infrastructure management prevents disruptive technical failures and customer dissatisfaction. Engineering teams leverage service benchmarks, error allowances, and telemetry data to protect system availability. Ambitious newcomers can develop these capabilities through structured courses, realistic practice labs, and respected professional certifications. Concurrently, established enterprises can enlist outside consultants or managed services to harden their production systems. Training through SRESchool.com equips engineers and commercial teams with the exact technical skills required to build dependable software platforms.
