Introduction
Modern enterprises require dependable information streams to execute profitable daily moves. Corrupted numbers mislead strategists, waste engineering payroll, and erode customer confidence. Siloed teams suffer through sluggish handoffs, failed file transfers, and ongoing deployment anxiety. Inside this detailed walkthrough, you will learn direct ways to repair fragile conduits and messy tables. Our review explores unattended batches, inline inspections, mandatory engineering skills, and comprehensive telemetric watchdogs. We also examine how industry platforms like TheDataOps.org publish straightforward roadmaps for builders. Clean operational habits harmonize staff members so corporate knowledge travels swiftly without unexpected breakdowns or distorted dashboards.
What Is DataOps?
Imagine an irrigation network delivering pure water directly to thirsty crops. Pure streams leave reservoirs, flow through filtering screens, and nourish plants evenly. Similarly, transactional entries leave checkout kiosks and land safely in business warehouses. DataOps gathers talented workers, standard evaluation methods, and purpose-built software to defend these waterways. It lifts rapid cycles from contemporary software teams, mainly Agile workflows and DevOps routines. Every team member targets one single priority: ship untainted facts quickly while protecting technical infrastructure from quiet outages. Because unattended routines execute frequent verifications, programmers drop boring manual duties and isolate defects before executives encounter bad charts.
Why Does DataOps Matter?
Aviation hubs and retail outfits rely on exact metrics to schedule flights, replenish inventory, and assist customers. Sluggish feeds strand knowledge workers, who then miss publishing their daily summaries on time. Unchecked files disappear, identical rows pile up, and unmonitored scripts halt without prior alert. Manual transfers between silos spawn bottlenecks because specialists must correct careless spelling mistakes by hand. Stale output forces supervisors to guess instead of using objective metrics for critical choices. DataOps resolves these expensive blockers by vetting tables before they populate executive views. Thus, teammates synchronize smoothly, remove operational waste, and supply accurate figures every morning.
What Is TheDataOps.org
TheDataOps.org functions as an educational knowledge ecosystem dedicated to resilient pipeline craftsmanship. The portal offers step-by-step documentation, plain-English tutorials, and practical diagrams for continuous integration systems. Its primary objective assists novice coders and seasoned administrators in operating stable data stacks. Members gain pragmatic perspectives on cloud storage topologies, orchestration engines, and productive cross-functional protocols.
DataOps Training and DataOps Course
Registering for structured DataOps Training arms developers with actionable tactics for building self-healing pipelines. An in-depth DataOps Course guides students through fast-moving Agile iterations and core DevOps disciplines. Learners implement CI/CD, which powers continuous builds, dynamic tests, and rapid deployments without downtime. The syllabus details cloud hosting environments, programmable audit scripts, and continuous health monitors. Constructing functional capstone projects yields the best returns because real experience prepares candidates for complex production crashes. Platforms like TheDataOps.org deliver hands-on modules so developers build durable enterprise architectures with complete confidence.
Comparison Table
| DataOps Area | Main Goal | Example Activity |
| Data Pipeline | Move data | Load daily sales data |
| Automation | Reduce manual work | Run jobs automatically |
| Testing | Find errors | Check missing values |
| Observability | Watch systems | Track failed jobs |
| Data Quality | Improve data | Check data rules |
| Orchestration | Manage steps | Run jobs in order |
DataOps Certification
Securing a DataOps Certification validates your grasp of fundamental pipeline design. The credential shows that you understand scripted unit checks, protected release tracks, and modern cloud deployment patterns. Even so, a paper award cannot substitute for persistent terminal practice. Applicants must combine syllabus studies with private sandbox clusters, open datasets, and original code repositories. A reliable learning progression starts with structured SQL queries, moves into Python automation, and culminates in end-to-end pipeline verification suites.
Data Pipeline Automation
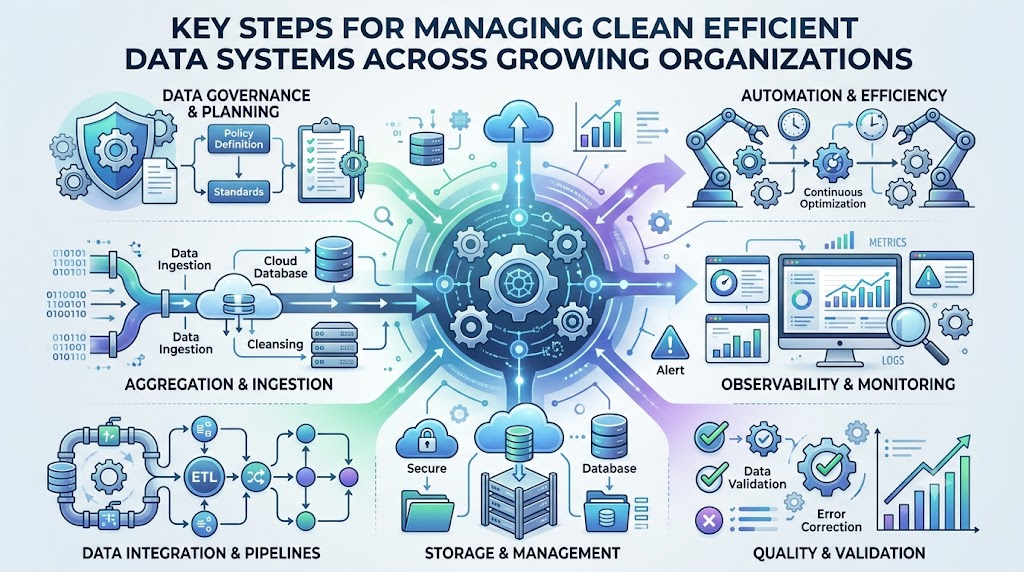
Data Pipeline Automation leverages background daemon scripts to extract and reshape assets without manual button presses. Triggering automatic jobs eliminates repetitive tasks that exhaust your programming staff. A standard automated sequence follows six distinct phases: Collect, Clean, Test, Process, Store, and Monitor. Picture a script pulling point-of-sale logs every midnight like clockwork. The routine strips empty columns, tallies customer charges, updates analytical tables, and triggers an operational receipt.
DataOps Tools
Engineering departments pick distinct DataOps Tools to crack specific puzzles across their technical environments. Developers write Python to sanitize dirty inputs, while Apache Airflow organizes tasks sequentially. Apache Kafka ingests live event streams, Apache Spark aggregates massive tables, and Hadoop retains bulk archive files. Meanwhile, Kubernetes balances containerized services, Jenkins oversees test runs, and Grafana produces live diagnostic screens. Analysts consult Power BI, Tableau, and cloud vendors like AWS to present key metrics clearly. Teams rarely need every tool on the market, so deploy only programs that address immediate infrastructure demands.
DataOps Platform
A modern DataOps Platform connects separated pipeline utilities within a unified workspace. This environment centralizes intake jobs, transformation scripts, test suites, execution calendars, alerting hubs, and access governance. Without a centralized hub, developers toggle through many browser tabs to track basic job runs. Before committing corporate funds, review tool integrations, pricing tiers, access controls, and horizontal scaling ceilings.
Data Observability
Data Observability gives administrators total visibility to inspect live transfers and pinpoint broken rows early. SRE teams watch system latency, row freshness, empty tables, broken runs, batch sizes, and hardware metrics. Picture a logistics engine processing five thousand package dispatches every single morning without failure. If a status monitor registers zero scans by mid-morning, an automated beacon fires instantly. Prompt alerts help technicians fix severed network cables long before regional directors view flawed delivery tallies.
Data Quality Management
Data Quality Management keeps company databases accurate, complete, and trustworthy for business analysts. Careless intake setups invite blank names, broken timestamps, duplicate identities, and scrambled numerical fields. When faulty figures enter executive briefings, managers make distorted calculations that undermine company operations. Scripted validation tests halt dirty batches at the gateway, verify mathematical rules, and segregate damaged inputs. Clean tables earn lasting confidence among decision-makers, who then shape corporate expansions with total assurance.
DataOps Consulting
Securing DataOps Consulting helps leadership uncover and dismantle hidden bottlenecks throughout their data departments. Experienced advisors audit legacy pipelines, persistent job errors, manual handoffs, and absent test suites. They evaluate diagnostic tools and deployment cadences so your organization can publish truthful metrics faster. High-value advisory engagements target measurable architectural snags without peddling magical enterprise panaceas.
Real-Life Scenarios / Experiences
- A regional grocer relied on manual workbooks for branch transfers, but clerical mistakes sent produce to closed facilities; applying automated checks flagged missing store codes immediately and stopped misrouted trucks.
- An insurance platform lost critical mornings to silent batch errors; configuring automated alerts summoned on-call engineers within two minutes of a drop, rescuing hundreds of billing hours.
- A diagnostic laboratory fought delayed patient workups; introducing an automated task coordinator delivered fresh blood panels before hospital doctors began their morning rounds.
DataOps Engineer Career Path
A DataOps Engineer erects sturdy highways so digital records travel smoothly without manual delays. Candidates chasing this profession must master core prerequisites like Python, SQL, Linux commands, and Git version control. Next, explore cloud warehouses, workflow schedulers, continuous delivery tools, and system log monitors. Build independent portfolio projects that pull open public archives, apply scripted checks, and populate tidy tables. Showcasing clean code on public hosting sites demonstrates to hiring leads that you engineer safe, scalable architectures.
Common Mistakes to Avoid When Choosing Delhi Events
- Reserving a hall without verifying calendar openings ruins scheduling goals; confirm event availability immediately.
- Overlooking maximum room occupancies invites severe overcrowding; balance attendance tallies with interior space limits.
- Skipping acoustic sound tests causes microphone failures; inspect amplifiers and speakers well before guests arrive.
- Ignoring venue parking restrictions causes traffic jams; choose locations featuring open, monitored parking areas.
- Selecting halls far from transit hubs slashes overall attendance; book spots near functional metro stations.
- Missing local permit deadlines brings municipal halts; secure necessary municipal clearance documents well in advance.
- Overlooking hidden facility charges breaks your budget; demand an itemized expense estimate prior to booking.
- Skipping catering samples results in disappointing meals; taste planned dishes before approving the catering contract.
How TheDataOps.org Can Help
TheDataOps.org delivers targeted, approachable materials for specialists who want to upgrade existing pipelines. Visitors can pursue guided paths for DataOps Training or prepare for an industry DataOps Certification. Self-directed practitioners can study a comprehensive DataOps Course to expand their hands-on implementation skills. The platform features practical reviews of DataOps Tools, pipeline platforms, and realistic DataOps Consulting concepts. Builders master Data Pipeline Automation, Data Observability, and Data Quality Management to succeed as an effective DataOps Engineer.
DataOps Tools
| Tool | Main Use | Simple Example |
| Python | Data coding | Clean data |
| Airflow | Job scheduling | Run pipelines |
| Kafka | Data streaming | Move live events |
| Spark | Data processing | Process large data |
| Jenkins | Automation | Run tests |
| Grafana | Monitoring | Watch system health |
Frequently Asked Questions
1. What does DataOps mean in simple words?
DataOps defines an operational philosophy that empowers software squads to publish clean data consistently. The discipline merges cross-functional talent, validation checks, and modern schedulers to guide production workflows. Picture an urban filtration grid that removes toxins before water meets local kitchens. Technical crews use these practices to remove human error, preserve developer bandwidth, and restore belief in core business metrics.
2. How does DataOps help business managers?
Business leaders gain verified statistics early each day to steer major commercial investments. The approach stops analysts from burning hours on manual workbook adjustments. Because automated systems move smoothly, departments complete deliveries rapidly and avoid expensive error recovery cycles. Executive teams rely on financial charts because automated validation guards defend every incoming database row.
3. What is a data pipeline?
A data pipeline represents a connected chain of automated scripts that transfers information across databases. The system ingests raw inputs from software apps, scrubs bad inputs, and stores structured records for review. Should an early stage fail, the entire sequence pauses and delays crucial business outputs. Automated pipelines execute on timers to keep executive dashboards current without human typing.
4. Why is automated testing necessary for data?
Automated tests inspect incoming records for missing inputs and invalid formats before staff view the output. When a check fails, the platform halts the job and isolates the suspicious batch instantly. This discipline blocks corrupt values from entering balance sheets and core customer databases. Consistent tests protect developers from exhausting night-shift debugging sessions on broken production tables.
5. What does a DataOps Engineer do each day?
A DataOps Engineer builds and monitors the digital avenues that carry records between corporate platforms. These specialists script automation programs, establish test bots, and manage cloud storage clusters. When a pipeline crashes, they inspect server logs and restore the broken connection rapidly. Their primary duty involves maintaining fast, protected, and tidy data delivery without manual bottlenecks.
6. Can small teams use DataOps methods?
Early-stage startups reap substantial gains from basic pipeline disciplines without buying expensive enterprise suites. Simple habits like storing code in Git repositories and running basic schema checks rescue countless hours every week. Adopting early hygiene preserves file order before transaction volumes expand into massive archives. Sensible working standards matter far more than purchasing premium platforms at the start.
7. What is the difference between DevOps and DataOps?
DevOps emphasizes the rapid creation and deployment of software products through automated code checks. DataOps applies those swift, structured principles to shifting database files and active pipelines. Software code remains predictable, whereas incoming business records change in size and layout every single hour. DataOps introduces specialized validation checks to process fluctuating records safely.
8. What is data observability?
Data observability involves tracking internal pipeline conditions continuously to uncover processing glitches fast. The setup measures run times, job terminations, record freshness, and abnormal row volumes. If a nightly job drops half its standard records, monitoring tools dispatch instant warnings. Early detection enables technicians to fix hidden pipeline failures before executives discover faulty numbers.
9. How do you start learning DataOps skills?
Begin your journey by mastering foundational tools like SQL for tables and Python for automation scripts. Next, practice Git commands for version tracking, Linux commands, and job schedulers like Airflow. Solidify your understanding by building an independent project that pulls internet records and executes automated validations. Reading direct tutorials on educational platforms like TheDataOps.org will accelerate your daily practice.
10. Does a certificate guarantee a high paying job?
A certificate demonstrates theoretical knowledge, yet the credential alone cannot ensure employment. Engineering directors prefer candidates who showcase functional scripts and working pipelines. Always support certification studies with public code portfolios that display your personal projects. Presenting active pipelines during interviews proves that you possess practical, real-world abilities.
11. What tools should beginners learn first?
Beginners should prioritize Python and SQL because both form the groundwork for modern data handling. Afterward, learn terminal navigation and Git to manage code files safely. Once comfortable, experiment with pipeline orchestrators like Apache Airflow to schedule recurring jobs. Introduce container systems like Docker and basic cloud storage once local scripts execute reliably.
12. Why do data pipelines fail unexpectedly?
Pipelines collapse when upstream services alter field formats without notifying database engineers. Network dropouts or full storage drives also trigger sudden job terminations. Without proactive alerts, these silent errors sit unaddressed until analysts notice inaccurate totals on final screens. Configuring automated validation checks catches these sudden crashes before damage spreads across the organization.
CONCLUSION
Consistent pipeline engineering unites scripted orchestration, continuous quality checks, and real-time observability to sustain resilient business architectures. When technical leaders break down team silos around standard platforms, organizations suppress manual errors, accelerate delivery, and protect commercial revenue. Forward-thinking learners and veteran developers can secure critical skills through structured study, official certification milestones, and production-style portfolio projects. Educational sites like TheDataOps.org present actionable breakdowns of leading toolsets and battle-tested workflows to help you build an enduring career. Master an unfamiliar data library today, automate a validation script, and fortify your enterprise pipelines step by step.
